Do LLM Bots Actually Use Cloudflare's Markdown for Agents?
We crunched logs for 25 days on several high traffic websites to test which bots are actually "asking for" / using Cloudflare's Markdown for Agents feature.
Field reports from a working GEO agency. Live case studies, methodology, and what we learn measuring ourselves first.
We crunched logs for 25 days on several high traffic websites to test which bots are actually "asking for" / using Cloudflare's Markdown for Agents feature.
We checked every request claiming to be an AI crawler on three sites against the operators' own published IP ranges. On a logistics company's site 28% was counterfeit, and 104 Google Cloud addresses were cycling up to sixteen crawler identities each.
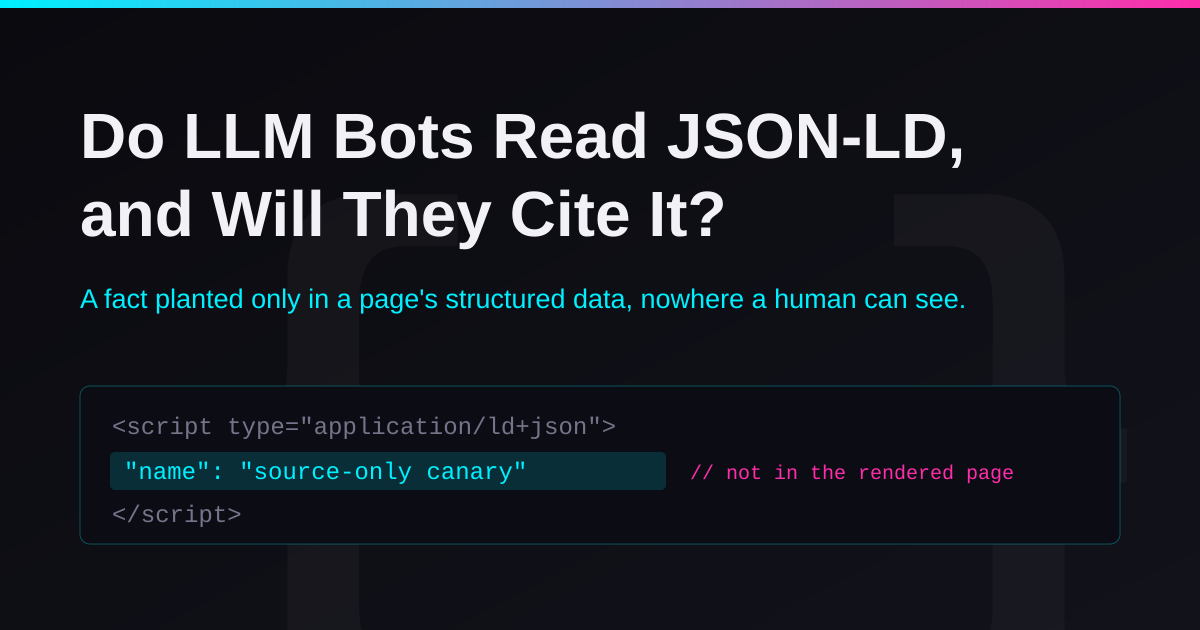
Result: yes, but only when they fetch the page. We planted a coined term where no human can see it, and Grok read all five planted terms straight out of our structured data - then showed us the curl command it used. The engines that answered from memory cited our competitors instead.
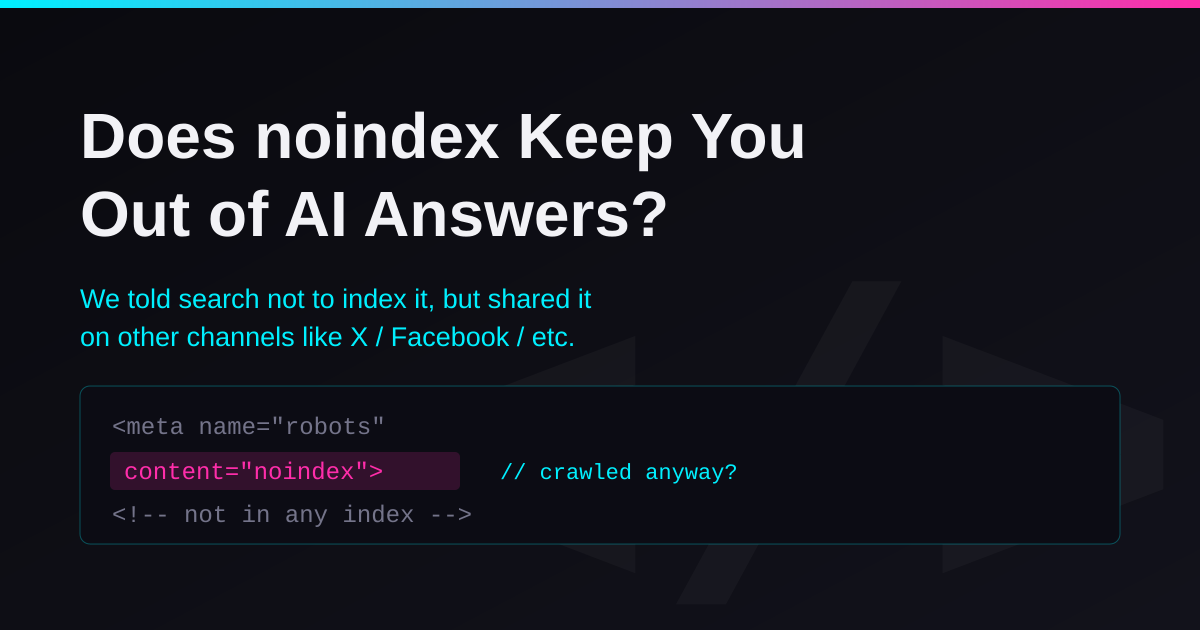
A live experiment: a noindexed page, never linked or listed, pushed out only by hand off-web - to test whether the AI engines ingest it anyway, and whether sharing alone is a route into AI answers.
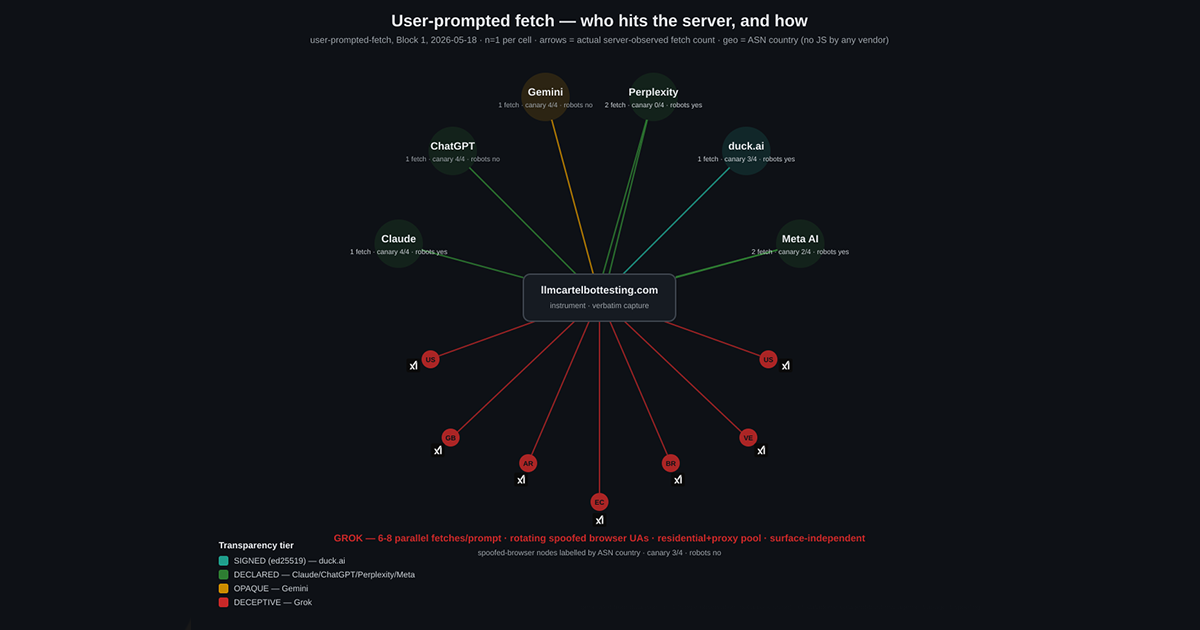
We logged what ChatGPT, Claude, Gemini, Grok and Perplexity actually fetch when you paste them a URL. Every one is JavaScript-blind - server-side proof for GEO and AEO.
We just turned llmcartel.com into a clean-slate experiment. The site is brand new. No external citations. No press. We started a clock to answer a question every founder asks: how long does it take an LLM bot to discover a new business entity?